The kubectl apply command is the main tool for creating, updating, and managing Kubernetes cluster resources. It allows the user to enforce the desired state of the cluster defined in a structured YAML or JSON manifest file.
This article explains the kubectl command, provides examples, and lists best practices for using it.
What Is kubectl apply Command?
The kubectl apply command is a declarative client-side and server-side tool for Kubernetes resource management. The command reads resource definitions from files, directories, or standard input streams, and forwards the specs to the Kubernetes API server (kube-apiserver).
Note: For a full reference of CLI operations, see the Kubectl Cheat Sheet.
While imperative commands issue concrete instructions (e.g., deleting a pod or scaling a deployment), kubectl apply provides the desired configuration. The API server evaluates the payload, calculates necessary diffs, and performs incremental updates without destroying or re-creating parameters that were not the subject of the configuration change.
Standard client-side kubectl apply uses an annotation on the kubectl.kubernetes.io/last-applied-configuration resource to track modifications across executions. The annotation stores a JSON copy of the manifest from the most recent successful apply operation.
For all subsequent updates, a three-way merge algorithm compares:
- The last-applied configuration (from the resource annotation).
- The current live state running in the cluster.
- The new target configuration provided in the local manifest file.
Kubernetes selectively modifies fields reconfigured in the local manifest, preserving live field alterations applied by external controllers, e.g., dynamic IP allocation or autoscaling replicas.
kubectl apply vs kubectl create
Both kubectl apply and kubectl create are used to create resources, but their underlying mechanisms and use cases differ.
kubectl create is an imperative command. It instructs the API server to create a new instance of a specified resource. If a resource with the same name and Kubernetes namespace already exists, kubectl create returns an error and halts execution.
Note: To overwrite an existing resource with kubectl create, either explicitly delete it beforehand, or include the --replace option. This action completely strips the existing object and substitutes it with the new definition.
kubectl apply is a declarative and idempotent command:
- If a specified resource does not exist,
kubectl applycreates it. - If the resource already exists,
kubectl applyapplies incremental modifications based on the aforementioned three-way merge logic.
The table below compares the two commands:
| kubectl create | kubectl apply | |
|---|---|---|
| Management Model | Imperative. | Declarative. |
| Idempotency | No (fails if resource exists). | Yes (safe to execute repeatedly). |
| Execution Path | Creates new object directly. | Creates or merges changes into existing object. |
| State Tracking | No tracking. | Injects last-applied-configuration annotation. |
| CI/CD Integration | High risk of pipeline failure on re-runs. | Recommended for automated pipelines. |
kubectl apply Command Syntax
The basic syntax for the kubectl apply command is:
kubectl apply (-f [filename] | -k [directory]) [options]The -f (or --filename) flag specifies the path to a file, directory, or URL with resource specifications. The -k (or --kustomize) flag targets a directory containing a kustomization.yaml file for dynamic configuration management.
kubectl apply Options
Optional flags can be used to modify kubectl apply execution. The table below introduces the important options:
| Option | Description |
|---|---|
--filename, -f | Path to a file, directory, or URL containing resource definitions. |
--kustomize, -k | Path to a Kustomize directory. |
--recursive, -R | Recursively processes subdirectories specified with-f. |
--dry-run=[client/server/none] | Simulates the operation. |
--server-side | Delegates merge decisions to the API server rather than client logic. |
--field-manager | Identifies the actor managing specific fields during server-side apply. |
--force | Replaces resources if conflicts cannot be resolved through standard merging. |
--prune | Deletes resources not present in the applied set (requires --selector). |
--selector, -l | Filters resources by label key-value pairs for --prune. |
kubectl apply Command Examples
The following examples show how to use kubectl apply in common deployment workflows.
Applying Resources directly from YAML Manifest
The standard application of a single manifest file updates or instantiates defined objects in the target cluster.
kubectl apply -f deployment.yamlThe output confirms the creation of the deployment:

When executing this command again after modifying deployment.yaml, the terminal reflects the update:

Applying Resources from URL
To stream manifest content directly from a remote location without local caching, type the URL of the manifest:
kubectl apply -f https://raw.githubusercontent.com/kubernetes/website/main/content/en/examples/controllers/nginx-deployment.yamlDeploying Entire Directories and Kustomize Configurations
Manifests can be grouped into a filesystem directory for easier access. Use the command below to process every valid manifest file inside a directory:
kubectl apply -f ./manifests/
Use the --recursive flag to include all subdirectories in a target directory:
kubectl apply -f ./manifests/ --recursiveWhen utilizing Kustomize for multi-environment overlays (such as staging or production variants), reference the directory containing kustomization.yaml with -k:
kubectl apply -k ./overlays/production/Updating Bare Metal High-Performance Storage Configurations
High-performance workloads like transactional databases or distributed storage layers need low-latency storage definitions. Carefully update manifests defining local persistent volumes (LocalPV) or direct block devices to preserve path references without dismounting raw block systems.
For example, the following is a storage manifest baremetal-storage.yaml that defines a storage configuration:
apiVersion: v1
kind: PersistentVolume
metadata:
  name: nvme-storage-node01
spec:
  capacity:
    storage: 1.6Ti
  volumeMode: Block
  accessModes:
  - ReadWriteOnce
  persistentVolumeReclaimPolicy: Retain
  storageClassName: local-nvme
  local:
    path: /mnt/disks/nvme0n1
  nodeAffinity:
    required:
      nodeSelectorTerms:
      - matchExpressions:
        - key: kubernetes.io/hostname
          operator: In
          values:
          - edge-node-01
To apply this configuration to the cluster, use the following command:
kubectl apply -f baremetal-storage.yamlIf the local device mount point shifts from /mnt/disks/nvme0n1 to /mnt/disks/nvme1n1, modify baremetal-storage.yaml and execute kubectl apply using the --server-side flag to validate against API rules:
kubectl apply -f baremetal-storage.yaml --server-side --field-manager=storage-admin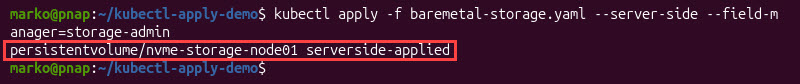
Validating Manifest Syntax with Dry-Run Execution
Prevent runtime disruptions by validating manifest structure before altering a live environment. A dry-run operation simulates an API submission without committing changes to the cluster database (etcd).
Evaluate the syntax locally by using client as the value in the --dry-run option:
kubectl apply -f application.yaml --dry-run=client
For a full schema validation, admission webhooks checks, and RBAC authorization verification, use the server value:
kubectl apply -f application.yaml --dry-run=serverPruning Obsolete Resources Automatically
Running standard kubectl apply commands does not remove live cluster components that stopped existing in local source code.
Clean up resources by using the --prune option and a label selector matching the target workload group:
kubectl apply -f ./manifests/ --prune -l app=analyticsThe command above scans the ./manifests/ directory, compares it against active cluster objects matching app=analytics, and removes any live resources missing from the manifests.
Managing Configurations via Server-Side Apply
Server-side apply transfers field ownership and merge calculations from the client binary to the kube-apiserver. It prevents conflicting edits between human administrators and automated CI/CD controllers.
kubectl apply -f service.yaml --server-side --field-manager=ci-pipelineIf another entity modified fields owned by ci-pipeline, the API server rejects the application and prints conflicting parameters. Force ownership reassignment with the following command:
kubectl apply -f service.yaml --server-side --field-manager=ci-pipeline --force-conflictsCommon Problems When Using kubectl apply Command
kubectl apply is designed to be reliable, but state errors or application failures can still appear in edge cases. Read the sections below for troubleshooting tips.
"Conflict" and Last-Applied-Configuration Mismatch Errors
When resources are managed through mixed paradigms, i.e., modifying an object imperatively using kubectl edit, kubectl scale, or kubectl patch, and later executed declaratively via kubectl apply, a mismatch can occur.
The error happens because imperative commands bypass updates to the kubectl.kubernetes.io/last-applied-configuration annotation, so the client-side three-way merge algorithm encounters conflicting base states. When used, the command may print a warning or overwrite imperative edits.
Note: If the annotation grows excessively large (for example, when embedding large raw configs in ConfigMap manifests), the operation fails due to annotation size limitations (exceeding 262,144 bytes).
To keep the current live cluster state and align the local YAML file with it for future kubectl apply runs:
1. Export the current live configuration (including imperative changes) to a local YAML file:
kubectl get -o yaml > updated-manifest.yaml2. Clean up runtime metadata from updated-manifest.yaml (remove fields like status, uid, resourceVersion, creationTimestamp, and existing kubectl.kubernetes.io/last-applied-configuration annotations).
3. Overwrite the annotation using the --overwrite flag:
kubectl apply -f updated-manifest.yaml --overwrite4. Confirm the annotation matches the updated file:
kubectl get -o jsonpath='{.metadata.annotations.kubectl.kubernetes.io/last-applied-configuration}'Field Management and Server-Side Apply Conflicts
For server-side apply, Kubernetes tracks field ownership using the resource's managedFields metadata array. If kubectl apply --server-side tries to change a parameter managed by a different entity (such as an ingress controller, horizontal pod autoscaler, or GitOps agent), the operation raises the following error:
error: Apply failed with 1 conflict: conflict with "helm" manager on path: spec.replicasTo resolve the error, omit the contested field from the local manifest, cede field ownership, or explicitly pass the --force-conflicts flag.
Attempting to Modify Immutable Fields
Some Kubernetes resource specification parameters are immutable after creation. For example, most fields in a PodSpec (such as spec.containers[*].name or persistent volume claim bindings) cannot be modified on a running pod instance.
If a local manifest attempts to change an immutable field, running kubectl apply throws an error, for example:
The Deployment "web-server" is invalid: spec.template: Invalid value: ... field is immutableTo replace resources with immutable field changes, re-create the object using:
kubectl replace --force -f [filename].yamlAlternatively, delete the object before executing kubectl apply.
Best Practices When Using kubectl apply Command
Follow the best practices below to optimize use of the kubectl apply command:
- Maintain manifests in version control. Store all resource specifications in a structured Git repository to maintain traceability, code reviews, and automated deployment auditing.
- Adopt server-side apply for pipelines. Utilize
kubectl apply --server-sidein CI/CD automation to leverage fine-grained field tracking and centralize merge logic within the API server. - Run server-side dry runs in validation steps. Integrate
--dry-run=serverchecks into pre-merge pull request tests to intercept syntax mistakes, schema mismatches, and authorization issues prior to production deployment. - Avoid mixing imperative and declarative operations. Refrain from running manual
kubectl editorkubectl patchcommands on resources managed viakubectl applyto prevent state tracking drift. - Define explicit field managers. Always provide a named
--field-manageridentifier when using server-side apply to track modifications cleanly across human operators and automated agents. - Consistently label resources for safe pruning. Apply standardized labels across manifests to safely use the
--pruneflag.
Conclusion
After reading this article, you should understand how to use the kubectl apply command in your cluster. The article covered the command's mechanics, syntax flags, and behavior, and provided troubleshooting steps and best-practice tips.
Next, read our Terraform vs. Kubernetes comparison guide.